By
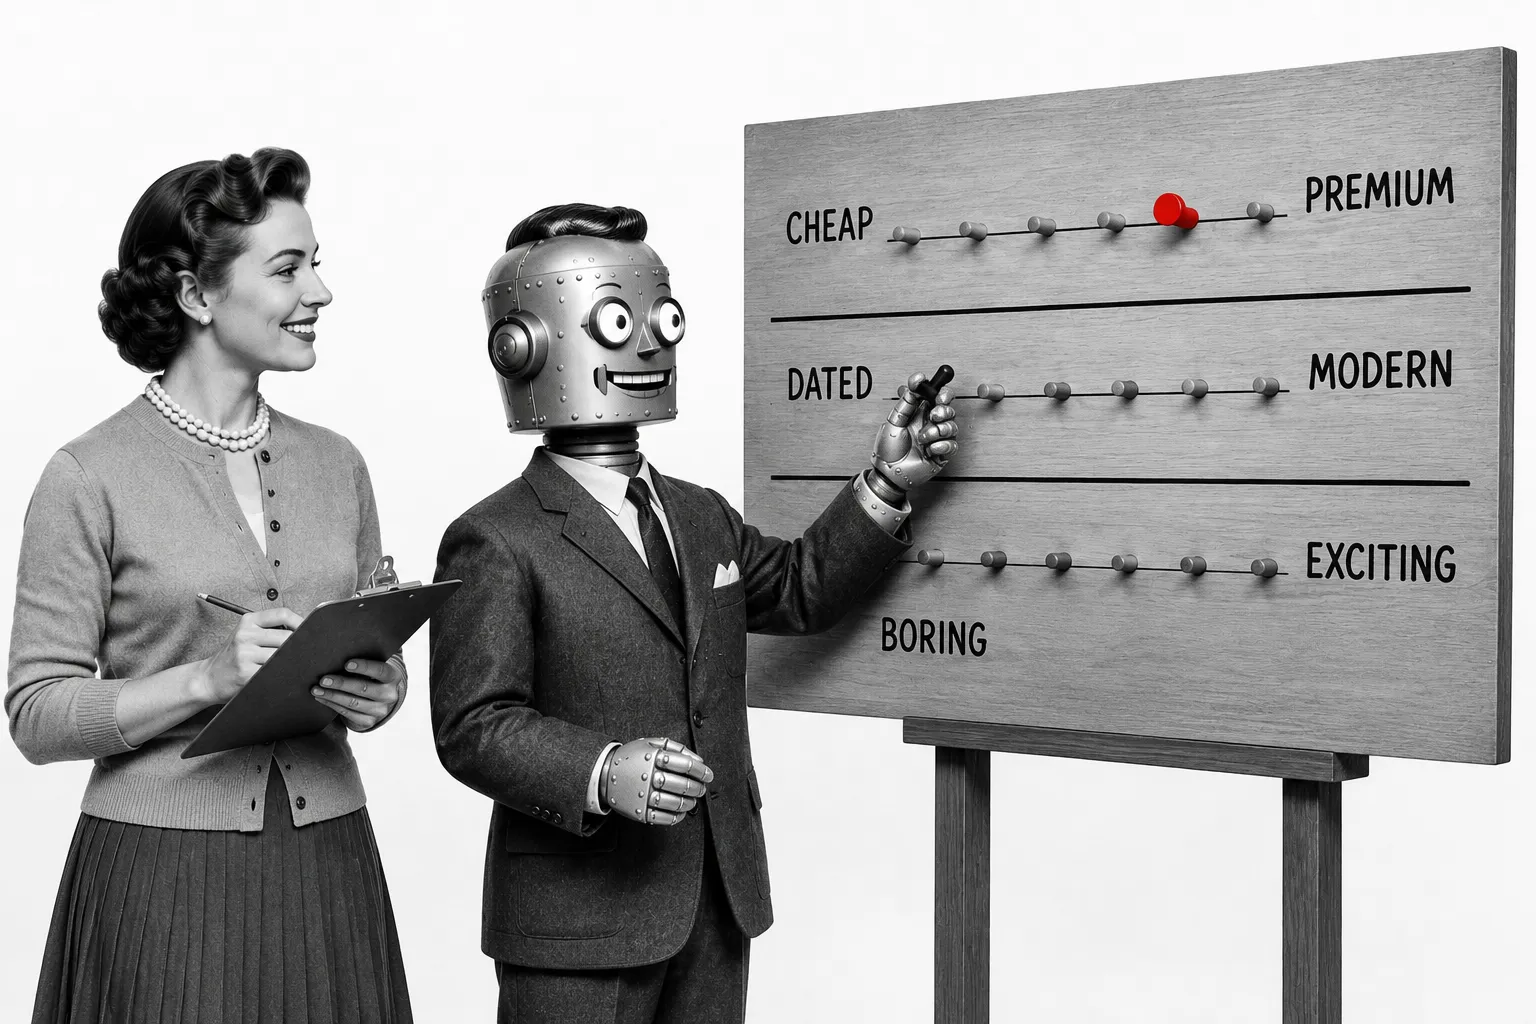
Most explainers of the semantic differential scale stop at “put an adjective at each end, a few points in the middle, ask people to mark a spot”. That is the easy half. The value is in choosing the right adjective pairs, knowing which of three hidden dimensions each one measures, and reading the answers as a profile rather than a single number you can quietly misread.
So here is what a semantic differential scale actually is, ready-to-use examples for an ecommerce brand, the three dimensions doing the work underneath, how it differs from a Likert scale, and how to read the results so they tell you something you can act on.
What a semantic differential scale is
A semantic differential scale asks a person to rate a concept between two opposite adjectives, on a fixed line of points. You name the thing being rated at the top, a brand, a product, a logo, an idea, then give a series of lines with a word at each end and nothing in between:
Cheap 1 · 2 · 3 · 4 · 5 · 6 · 7 Expensive
The respondent marks the point that matches how they see it. Do that across a handful of adjective pairs and you have mapped their perception of the concept along several attributes at once.
The technique comes from the psychologist Charles Osgood, who proposed it in a 1952 paper in Psychological Bulletin and set it out in full in The Measurement of Meaning in 1957, written with George Suci and Percy Tannenbaum. Osgood was not trying to measure satisfaction or agreement. He was trying to measure meaning: the connotations a word or object carries in someone’s head. That origin matters, because it is why the scale is so good at brand image and so weak at things people can just tell you directly.
Two design features define it. The ends are bipolar, genuine opposites rather than “agree” and “disagree”. And the classic format is seven points, though five is common and works well. Everything else, the number of pairs, which adjectives, how you label the points, is a choice you make, and those choices decide whether the data means anything.
Semantic differential scale examples
The trick is matching the adjective pairs to the decision in front of you. Here are three sets built for an ecommerce store, each aimed at a different job.
Brand perception. Run this when you want to know how your brand sits in people’s heads, ideally against a competitor rated on the same lines.
Concept: [Your brand]
- Cheap 1 · 2 · 3 · 4 · 5 · 6 · 7 Premium
- Old-fashioned 1 · 2 · 3 · 4 · 5 · 6 · 7 Modern
- Unreliable 1 · 2 · 3 · 4 · 5 · 6 · 7 Reliable
- Impersonal 1 · 2 · 3 · 4 · 5 · 6 · 7 Personal
- Boring 1 · 2 · 3 · 4 · 5 · 6 · 7 Exciting
Product page or a specific product. Use this to test how a product reads before or just after launch, on the attributes that drive the buy.
Concept: [Product name]
- Poor quality 1 · 2 · 3 · 4 · 5 · 6 · 7 High quality
- Overpriced 1 · 2 · 3 · 4 · 5 · 6 · 7 Good value
- Complicated 1 · 2 · 3 · 4 · 5 · 6 · 7 Simple
- Ordinary 1 · 2 · 3 · 4 · 5 · 6 · 7 Distinctive
- Hard to trust 1 · 2 · 3 · 4 · 5 · 6 · 7 Trustworthy
Packaging or a piece of creative. This is where semantic differential earns its keep, because reactions to design are exactly the kind of half-formed impression people struggle to put into words.
Concept: [Pack design A]
- Cluttered 1 · 2 · 3 · 4 · 5 · 6 · 7 Clean
- Cheap-looking 1 · 2 · 3 · 4 · 5 · 6 · 7 Premium
- Forgettable 1 · 2 · 3 · 4 · 5 · 6 · 7 Eye-catching
- Confusing 1 · 2 · 3 · 4 · 5 · 6 · 7 Clear
- Dated 1 · 2 · 3 · 4 · 5 · 6 · 7 Contemporary
A few rules sit behind these. Keep every pair a true opposite, so “premium” pairs with “cheap”, not with “not premium”. Keep the pairs relevant to the concept, because a coffee brand rated on “fast to slow” produces noise. And do not rate two different concepts on one grid in a way that lets people compare as they go. Rate your brand fully, then the competitor, so each gets an honest read.
The three dimensions doing the work
This is the part that makes the scale more than a row of adjectives.
When Osgood and his colleagues ran factor analysis across huge sets of semantic differential ratings, they found that the adjective pairs were not independent. They collapsed onto three recurring dimensions, which the field shortens to EPA:
Evaluation. Good versus bad. Pleasant versus unpleasant. Valuable versus worthless. This is the “do they like it” dimension, and it is the one most marketers actually care about, because it carries the feeling behind the rating.
Potency. Strong versus weak. Powerful versus feeble. Large versus small. This is about the force or presence of the thing.
Activity. Active versus passive. Fast versus slow. Lively versus dull. This is about energy and movement.
The practical payoff is that these dimensions can move independently, and reading them separately stops you drawing the wrong conclusion. A brand can score high on evaluation, people like it, while scoring low on potency, it feels a bit weak and easy to overlook on a shelf. That is a completely different problem from a brand people dislike, and a bare overall average would blur the two together. When you pick your adjective pairs, it is worth knowing which dimension each one taps, so you are measuring the thing you actually want to move, usually evaluation for likeability and potency for shelf standout.
Semantic differential vs Likert scale
These get muddled constantly, and the difference is simple once you see it.
A Likert scale gives you a statement and asks how strongly you agree: “This brand feels premium”, from strongly disagree to strongly agree. A semantic differential gives you the concept and two opposite words, “cheap to premium”, and asks where it sits. One measures agreement with a claim you have written. The other measures perception along a spectrum you have defined.
That leads to different strengths.
| Semantic differential | Likert scale | |
|---|---|---|
| What it measures | Perception of a concept between two poles | Agreement with a statement |
| Best for | Brand image, packaging, mapping several attributes | Satisfaction, attitudes, feedback on something owned |
| Question shape | Bipolar adjectives, no statement | A statement plus agree-to-disagree |
| Reads well as | A profile across many pairs | Top-two-box on each item |
Use a Likert scale when you have a specific claim to test or a satisfaction question to track. Reach for a semantic differential when you want to map how something is perceived across several attributes at once, especially the soft, image-led attributes that are hard to phrase as a clean statement. Neither is more rigorous than the other. They answer different questions.
How to build one that gives clean data
The scaffolding is easy. The details are where surveys quietly go wrong.
Pick the concept and keep it single. One brand, one product, one pack per grid. If you are comparing two, run two grids on the same pairs, not one grid that invites people to see-saw between them.
Choose the adjective pairs deliberately, then pilot them. Start from the attributes that matter to the decision, write a genuine opposite for each, and test the list on a few people before you run it properly. Osgood himself recommended a pilot step to find the pairs that actually discriminate, because an adjective that everyone rates the same way tells you nothing.
Keep the grid short: five to eight pairs. There is no magic number, but there is a real ceiling, and it comes from two problems this post has already named. A long bipolar grid is genuinely hard to complete on a phone, which is the same argument that pushes you towards five points rather than seven. And the longer the grid runs, the more likely someone stops reading and draws a straight line down the page, which is the exact behaviour the direction-varying trick below exists to catch. Five to eight pairs per concept keeps both problems small. If you have twenty attributes you care about, that is a sign the study has not decided what it is for, and the fix is to cut the list rather than make people work harder.
Pick five or seven points. Seven is the classic format and gives more room for nuance, which suits brand and attitude work. Five is faster and cleaner on mobile. Both are defensible; pick one and hold it steady across the survey and over time.
Label the ends clearly, and do not fret about the middle. Garland (1990), testing labelled, numbered and blank scale points on a sample of shoppers, found no significant difference in the ratings the three forms produced, but respondents clearly preferred the labelled version and found it easiest to use. So the format barely changes your data, which means you can choose the one people find easiest without worrying it will bias the result. Put a clear word at each end.
Vary the direction of the positive pole. If the “good” end is always on the right, some people stop reading and run a straight line down the page. Flip a few pairs so the positive adjective sits on the left, then flip the scores back before you analyse. It costs you a moment of processing and buys you honest answers.
How to read the results: the profile, not the average
This is where the scale rewards you, and where most write-ups say “calculate the mean” and leave you to it.
Take the average of each adjective pair across your respondents and plot those averages down the page. That line, the pattern across all the pairs, is called the profile, and the shape is the insight. A brand that runs high on quality and trust but sags on “exciting” and “distinctive” has a clear, specific story, and you would never have seen it from one blended score.
The profile earns its power from comparison. Plot your brand’s profile next to a competitor’s on the same pairs and the gaps jump out: maybe you are level on modern and reliable but a full two points behind on premium. Plot this quarter against last and you can see perception move, which is the same discipline behind tracking brand awareness over time. A profile on its own is a shape without a ruler. Against a benchmark, it is a brief.
Two honest cautions, because reading these scales naively is easy.
First, the numbers are not as precise as they look. The points are ordered, but the gap between a 5 and a 6 is not guaranteed to equal the gap between a 6 and a 7, so averaging assumes a little more than the scale strictly gives you. Heise (1969), reviewing the method in Psychological Bulletin, put it plainly: the metric assumptions are in some ways inaccurate but adequate for many applications. Averaging to build a profile is standard and fine for spotting differences. Just do not oversell a 0.2 gap as meaningful.
That raises the question the write-ups never answer: how big does a gap have to be before it is real? Work it from your sample. On a seven-point scale, ratings usually scatter with a standard deviation somewhere around 1.4, so at 100 respondents per concept the ninety-five per cent interval around the difference between two means is roughly four tenths of a point. Below that you are reading noise. Two hundred per concept tightens it to about a quarter of a point, and as with any sample, halving the interval costs four times the people. The working rule for most brand and pack work: field at least a hundred per concept, and treat any gap under half a point as a tie. That sounds strict until you count how many profile charts get presented on a triumphant 0.3 point lead.
Second, watch the concept-scale interaction. The same adjective can mean different things against different concepts: “fast” is a compliment for a delivery service and neutral for a cushion. Heise flagged this as one of the real traps, noting that genuine scale-concept interactions mean you should tailor your adjective pairs to the thing you are rating rather than reusing a generic grid. Add the usual social desirability pull, where people rate towards what sounds good about themselves, and the rule follows: pick pairs that fit the concept, and read the shape and the comparison rather than any single point.
When a semantic differential is the wrong tool
A semantic differential measures how people perceive something that is in front of them. That is exactly right for a brand you already have, a pack you can show, a product people can hold or see. It maps the impression, and it does it well.
It is much weaker for predicting a decision that has not happened yet. Rating an unlaunched product as “high quality” and “good value” tells you the idea reads well. It does not tell you anyone will part with money for it, and the gap between a flattering perception and an actual purchase is wide and well documented. Plenty of concepts that profiled beautifully still launched flat.
So if you are about to spend real money on a new product, a pack, a price or a claim, pair the perception read with a measure of intent, and get the reasons in people’s own words, because the verbatims are usually where the value sits. Our roundup of voice-of-customer tools covers the kit for reading those reasons at scale.
For the pre-launch case there is a harder gap: often there is nobody to survey yet. That is what TestFeed is built for. You put a product, a pack, an in-context price, an ad or a concept in front of shoppers modelled on your target customer and get back a purchase-intent read, their reasons in their own words and a clear next move, in days rather than weeks. Treat it as directional pre-spend signal for deciding what deserves a real launch, not a sales forecast or a guaranteed number, and note it does not judge taste, texture or smell. If you want to see how that differs from a survey panel, the comparison with a purpose-built test audience is the thing to read next. Then, once something is live, point a semantic differential at how people perceive it and track the profile over time.
Frequently asked questions
What is a semantic differential scale?
A semantic differential scale is a survey question that asks people to rate a concept between two opposite adjectives, such as cheap and expensive or boring and exciting, usually on a seven-point line. The psychologist Charles Osgood and his colleagues introduced it in The Measurement of Meaning in 1957 to capture the meaning people attach to a word, brand or object. Instead of asking whether someone agrees with a statement, it asks where their perception sits between two poles.
What is an example of a semantic differential scale?
Rating a brand from 1 to 7 on the pair cheap to expensive, then on old-fashioned to modern, then on unreliable to reliable, is a semantic differential scale. Each line has an opposite adjective at each end and no words in the middle. The respondent marks the point that matches how they see the brand, and you build a profile from the average of each line.
What is the difference between a semantic differential scale and a Likert scale?
A Likert scale measures how strongly someone agrees with a statement, from strongly disagree to strongly agree. A semantic differential scale places a concept between two opposite adjectives and asks where the person’s perception falls. Use a Likert scale for agreement and satisfaction questions, and a semantic differential when you want to map how a brand or product is perceived across several attributes at once.
How many points should a semantic differential scale have?
Five or seven. Seven is the classic Osgood format and gives respondents more room to place themselves, which suits brand and attitude work. Five is faster and reads better on a phone. Garland (1990) found that labelling the points, numbering them or leaving them blank made no significant difference to the ratings, but respondents clearly preferred the labelled form, so label the ends clearly whichever length you pick.
How many adjective pairs should a semantic differential scale use?
Five to eight per concept is the practical range. There is no fixed rule, but long bipolar grids are hard to complete on a phone and they encourage respondents to stop reading and draw a straight line down the page, which ruins the data. Keep the pairs to the attributes that actually bear on the decision. If your list runs to twenty, the study has not decided what it is for, and the fix is to cut the list rather than make people work harder.
What are the three dimensions of the semantic differential?
Evaluation, potency and activity, often shortened to EPA. Osgood and colleagues found through factor analysis that most adjective pairs load onto one of these three. Evaluation is good versus bad, potency is strong versus weak, and activity is active versus passive. Evaluation is the dimension most marketers care about, because it captures whether people feel positively or negatively about the thing being rated.
Where to start
The next step is not more adjective pairs. Pick the handful that map to the decision in front of you, put a clear word at each end, vary which side the positive pole sits on, and read the answers as a profile against a competitor or your own target rather than a single blended score. Do that and the scale will show you exactly where your brand stands and what to move.